Human-edited content at scale: roles, loops and limits
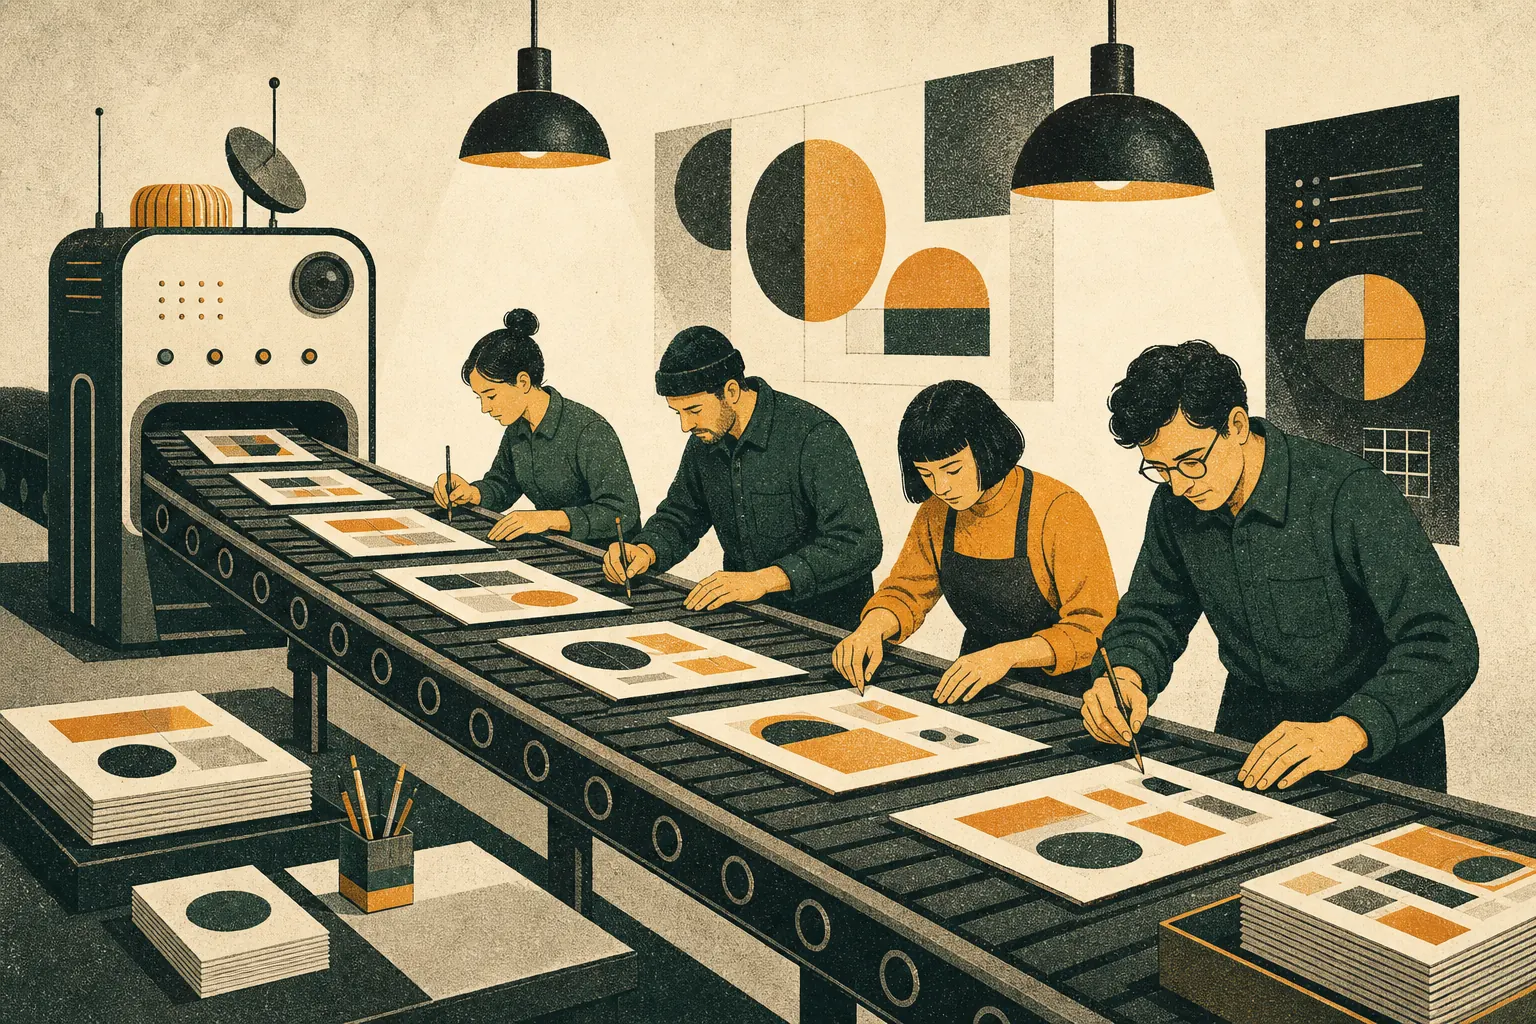
Human-edited content at scale means using AI for drafting and variation while people own voice, judgment and approval. It works when review is tiered by risk, editors focus on judgment rather than repair, edit patterns feed back into prompts and voice rules, and audience evidence keeps content relevant. Scale comes from the system, not from removing editors.
What does "at scale" really mean?
For some teams it means fifty product pages a week; for others, hundreds of localised social variations or thousands of catalogue descriptions. The numbers vary, but the problem is the same: volume grows faster than the number of people who can read carefully. In 2020, scale with GPT-3 was barely possible because every output needed close review. Now drafting is effortless and review is the constraint.
Which roles make it work?
- Voice owner: maintains the voice system and settles disputes about what is on-brand.
- System owner: maintains prompts, templates and the prompt library.
- Editors: review, correct and approve, and log the categories of edits they make.
- Fact checker: verifies claims for higher-risk content.
- Insight lead: keeps audience evidence current and connects performance back to inputs.
In small teams one person may wear several hats. The point is that each responsibility is named.
How do you tier review?
Tier 1: full review
Claims, regulated categories, sensitive topics, crisis communication, high-reach campaigns. Every piece is read and approved by an editor, with fact checks where needed.
Tier 2: standard review
Regular brand content. Every piece is read; edits focus on voice and judgment.
Tier 3: sampled review
Low-risk variations from an approved master, such as format adaptations. An editor approves the master and reviews a sample of the variations, escalating if issues appear.
Tiering is not about trusting the model more. It is about spending human attention where the risk and the reward are highest.
How do feedback loops reduce editing over time?
Every edit is information. If editors keep removing the same phrase, add it to the banned list. If they keep adding customer context, the brief template is missing audience inputs. A monthly review of edit logs, owned by the system owner, turns repeated corrections into upstream fixes. We covered the categories in why AI drafts still need heavy editing.
Where do humans add the most value?
- Deciding what is worth saying at all
- Choosing the sharpest angle from several drafts
- Spotting tone that is technically fine but wrong for the moment
- Protecting accuracy and the brand's honesty
- Noticing when audience sentiment has shifted
That last point is where audience evidence helps. SOMIN, an AI audience-research platform and our technology partner, surfaces shifts in tone and tension from real posts, so editors are not relying on instinct alone. Teams scaling social output often pair this with the SOMIN social media manager.
What are the limits?
Scale has a ceiling set by attention. Push sampled review too far, or let tier 1 content slip into tier 3, and errors reach the public. If edit logs show quality falling, slow down. Volume that damages trust is not efficiency.
Checklist: scaling safely
- Named owners for voice, system, editing and insight
- Review tiers defined and documented
- Edit logs kept by category
- Monthly loop from edit logs to prompts and voice rules
- Audience evidence refreshed regularly
- Clear escalation path for sensitive content
Definitions
- Review tier: a level of human scrutiny assigned by content risk.
- Master and variation: an approved core piece and its adapted versions.
- Escalation: moving content to a higher review tier when issues appear.
Agents and editors
As agentic workflows take on more steps, from research to drafting to scheduling, the same principle holds: agents run the process, humans own judgment. Our sister agency AgentC works this way. For further reading on teams combining insight and execution, see the Havas Media case study.
How do you onboard editors to AI-assisted work?
Editing machine drafts is a different skill from editing human writing. Human drafts tend to have an intention you can sharpen; machine drafts are often smooth but empty, with the point buried or missing. New editors need practice spotting fluent emptiness.
A practical onboarding sequence takes about a week:
- Read the voice system and the narrative, then rewrite three generic drafts into on-voice pieces.
- Shadow an experienced editor through a day of tier 2 review, discussing each decision.
- Edit a batch independently and compare with a senior editor's version.
- Start logging edits by category from day one.
Also teach editors when to reject a draft entirely and fix the brief instead. Rewriting from scratch every time hides the real problem and burns the time that scale was meant to save.
What does a good week look like?
In a healthy operation, editors spend most of their time on tier 1 and tier 2 judgment, sampled reviews raise few issues, and the monthly loop produces one or two small changes to prompts or voice rules. If editors are rewriting most drafts, return to inputs before adding headcount.
Where does audience insight sit in the loop?
The insight lead closes the loop between what was published and what the audience said back. Monthly, they compare response signals with the themes and phrases in briefs, and flag gaps to the system owner. Without this step, the operation gets efficient at producing content that slowly drifts away from its readers.
Treat that comparison as a standing agenda item rather than an occasional project. Small, regular corrections keep the system close to its readers and stop a drift that would otherwise need a full audit to fix.
Frequently asked questions
Can you scale content without scaling editors proportionally?
Yes, by tiering review, improving inputs and focusing editors on judgment rather than repair. Volume can grow faster than headcount, but not without any human review.
What roles does an AI-assisted content team need?
Typically a voice owner, prompt or system owner, editors, a fact checker for higher-risk content, and someone responsible for audience insight and measurement.
What content should always get full human review?
Anything with claims, legal or health implications, sensitive topics, crisis communication, or high reach. Lower-risk variations can use lighter sampled review.
Book a voice audit
We have been writing with language models since the summer the GPT-3 API opened in 2020. We build brand voice systems, prompt libraries and human-edited content operations, grounded in what your real audience responds to.
Email ask@gpt3.marketing →